
Global and regional language coverage.
Annotators, linguists, and domain specialists.
Your labels, taxonomies, and data structures.
Calibration, validation, agreement, and review.
What Is Multilingual Text Annotation?
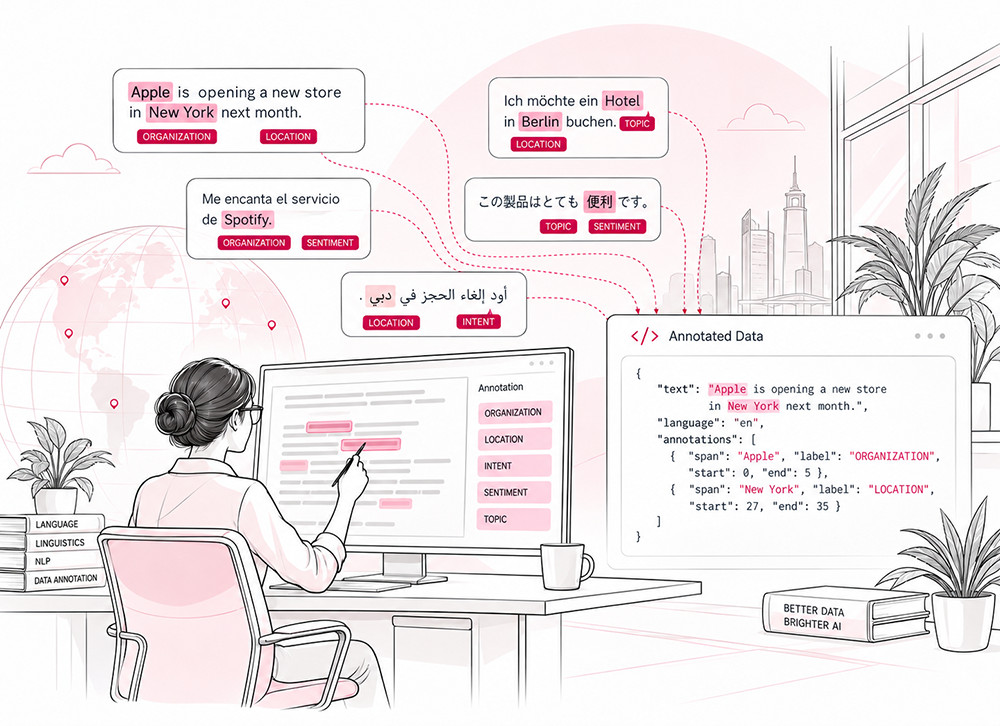
Multilingual text annotation adds structured labels, categories, attributes, relationships, rankings, or other metadata to text so AI and machine-learning systems can use it effectively.
Depending on the application, annotation may identify people and organizations, classify customer intent, determine sentiment, assign topics, label unsafe content, evaluate search relevance, or map semantic relationships between concepts.
Text annotation is different from translation. Translation changes the language of the content, while annotation adds structured information that can support model training, fine-tuning, retrieval, classification, and other AI-data workflows.
Multilingual annotation introduces an additional challenge: the same schema must work across languages that differ in grammar, segmentation, terminology, cultural conventions, and real-world usage. Reliable programs therefore need language-aware guidelines, qualified contributors, calibration, and quality controls designed for global datasets.
Multilingual Text Annotation for Modern AI Systems
Stepes supports both established NLP annotation and increasingly sophisticated AI-data labeling workflows. Projects can use standard frameworks or custom schemas built around your data, model, taxonomy, and business requirements.
Named Entity Recognition & Span Annotation
Identify and label meaningful spans of text such as people, organizations, products, locations, dates, events, medical concepts, legal terminology, financial entities, and custom domain-specific information. Stepes supports standard NER as well as project-specific span, attribute, and entity-label frameworks.
Intent Classification
Classify the purpose behind user queries, support requests, messages, and conversational inputs. Native-language annotators apply consistent intent taxonomies while accounting for the different ways users naturally express the same need across languages, regions, and communication styles.
Sentiment & Emotion Annotation
Label text by sentiment, emotion, tone, or project-specific attitudinal categories. Language-aware review helps capture sarcasm, indirect language, humor, idioms, and culturally dependent expressions that literal analysis can miss.
Text Classification & Multi-Label Categorization
Organize multilingual text into structured categories using single-label, multi-label, hierarchical, or custom classification frameworks for document routing, content filtering, risk categorization, product classification, and enterprise knowledge management.
Topic & Taxonomy Tagging
Apply structured topics, categories, and metadata using customer-defined taxonomies. Consistent multilingual taxonomy annotation improves discovery, recommendation, knowledge organization, and downstream machine-learning workflows while preserving legitimate local distinctions.
Relationship & Semantic Annotation
Identify relationships between entities, concepts, actions, events, and other elements within text. Projects can capture entity relationships, semantic roles, attributes, subject-object links, cause-and-effect relationships, and domain-specific associations.
Search & Retrieval Relevance Annotation
Improve multilingual search, semantic retrieval, and ranking systems with human judgments for query-document relevance, result quality, semantic matching, and relevance grading. Native-market review helps capture terminology, query behavior, and local user expectations.
Content Safety & Moderation Annotation
Build multilingual trust-and-safety datasets against customer-defined policies for harmful, abusive, sensitive, offensive, or restricted content. Locale-aware contributors help interpret slang, euphemisms, insults, coded language, and culturally sensitive terminology in context.
Preference & Response Labeling
Create structured human labels for AI-generated responses and preference datasets used in supervised fine-tuning, model alignment, and related training workflows. Projects can include response classification, pairwise preference, quality labels, and task-specific response attributes when the goal is to create training or preference data rather than approve generated content for publication.
Multilingual LLM Evaluation ServicesDomain-Specific Annotation
Match complex datasets with linguists and domain specialists experienced in areas such as life sciences, healthcare, legal, financial services, technology, manufacturing, and other specialized fields where terminology and subject-matter context materially affect annotation decisions.
Multilingual Annotation Across the AI Lifecycle
High-quality annotation supports AI systems across training-data preparation, search and retrieval, conversational AI, trust and safety, and ongoing model improvement.
NLP & Machine Learning
Create structured multilingual training and validation data for classification, extraction, semantic analysis, and specialized NLP systems.
Conversational AI
Improve chatbots, assistants, and agents with intent labels, entity annotations, utterance classification, dialogue metadata, and locale-specific judgments.
Search, Ranking & Retrieval
Provide human relevance judgments for search engines, ranking models, recommendation systems, and retrieval pipelines across languages.
LLM Training & Fine-Tuning
Create labeled datasets for supervised fine-tuning, response classification, preference learning, instruction tuning, and related model-development workflows.
RAG & Enterprise Knowledge
Support retrieval-augmented generation with metadata, taxonomy annotation, relevance judgments, classification, entity tagging, and document relationships.
Trust & Safety
Develop multilingual safety datasets that reflect real-world language, regional vocabulary, cultural context, and evolving user behavior.
Multilingual Annotation Is More Than Translating English Labels
A taxonomy that works in English does not automatically produce reliable annotation in every other language. Successful programs combine global consistency with local linguistic accuracy.
Language Structure & Segmentation
Languages differ in morphology, word boundaries, compounds, grammar, and sentence formation. These differences can affect span boundaries, token-level labels, entity detection, and intent classification.
Entity & Naming Conventions
Names, addresses, titles, organizations, products, dates, and other entities are expressed differently across markets. Language-aware annotation helps keep entity boundaries and types locally accurate.
Intent & Real-World Expression
Users can communicate the same goal with different levels of directness, formality, context, or implied meaning. Native-language annotators classify the underlying intent rather than relying on literal wording.
Sentiment, Tone & Pragmatics
Sarcasm, politeness, irony, humor, indirect criticism, and emotional intensity can substantially change meaning and often require professional linguistic judgment.
Safety & Cultural Context
Slang, euphemisms, coded speech, insults, and sensitive terminology vary by community and locale. Native-market expertise helps interpret them within a consistent global policy framework.
Global Schema Consistency
The goal is not only local correctness. Labels must remain comparable across languages. Shared rules, calibration, and documented decisions help preserve cross-language consistency without erasing legitimate differences.
The Right Expertise for Every Annotation Task
Different annotation projects require different levels of linguistic, technical, and subject-matter expertise. Stepes builds teams around task complexity, target languages, content domain, and quality requirements.
Native-Language Annotators
Trained native-language contributors support high-volume tasks where natural language understanding and local-market knowledge are essential.
- Intent classification
- Search relevance
- Content categorization
- Moderation labels
- User-generated content
Professional Linguists
Professional linguists support annotation work that depends on deeper semantic, linguistic, cultural, or terminology-sensitive judgment.
- Ambiguous language
- Semantic relationships
- Complex span annotation
- Sentiment and tone
- Cross-language consistency
Domain Specialists
Specialized datasets can include reviewers who understand both the target language and the subject matter, helping protect technical meaning and terminology.
- Life sciences
- Legal
- Financial services
- Technology
- Industrial and technical content
Quality Built Into Every Annotation Dataset
Reliable AI data requires more than accurate individual labels. It needs a repeatable framework that aligns contributors, identifies ambiguity, validates output, and captures decisions that can be applied consistently across the dataset.
Depending on project needs, Stepes annotation workflows can incorporate guideline review, calibration, independent overlap, gold-standard examples, inter-annotator agreement, secondary review, and adjudication.
Guideline Review
Clarify label definitions, decision rules, positive and negative examples, edge cases, taxonomy structure, language-specific considerations, and expected deliverables before production.
Annotator Calibration
Use representative samples to identify inconsistent interpretations, unclear labels, missing examples, and language-specific edge cases before scaling the full dataset.
Production Annotation
Complete annotation according to approved guidelines while centralized program management supports consistency across languages and contributor groups.
Validation & Overlap
Apply the appropriate mix of secondary review, independent overlap, gold-standard examples, automated validation, sampling, consistency checks, and error categorization.
Inter-Annotator Agreement
Where multiple independent judgments are used, agreement metrics help identify ambiguous guidance, difficult edge cases, and opportunities for further calibration.
Adjudication & Improvement
Resolve disagreements through experienced reviewers and feed adjudication decisions back into examples and guidelines so later annotation rounds remain consistent.
A Scalable Workflow From Schema to Model-Ready Data
Stepes provides a structured multilingual annotation workflow that can scale from pilot datasets to ongoing global AI-data programs.
Define
Align the AI use case, source data, languages, annotation objectives, volume, quality requirements, and technical deliverables.
Design
Confirm schemas, taxonomies, guidelines, decision rules, examples, edge cases, and output requirements.
Calibrate
Run representative sample tasks so interpretations can be compared and clarified before full production.
Annotate
Scale production across approved languages with contributor profiles matched to task and domain complexity.
Validate
Apply the agreed QA model, which can include review, overlap, automated validation, sampling, agreement analysis, and adjudication.
Deliver & Iterate
Provide structured output in the agreed format and incorporate downstream feedback into subsequent annotation rounds.
Structured Data That Fits Your AI Workflow
Annotation data should fit the systems that use it. Stepes supports common structured formats and customer-defined delivery requirements so datasets can move efficiently into training, fine-tuning, search, analytics, and other AI workflows.
Formats & Annotation Structures
Deliverables can be aligned to project schemas, identifiers, validation rules, and downstream technical requirements.
- Classification labels
- Entity spans
- Character or token offsets
- Entity attributes
- Semantic relationships
- Hierarchical categories
- Multi-label values
- Reviewer metadata
- BIO/BILOU labels
- Project-specific fields
Flexible Workflow Integration
Stepes can work within agreed project workflows, supported annotation environments, or approved client tools based on technical, security, and operational requirements.
{
  "id": "sample_00428",
  "locale": "fr-FR",
  "text": "Je souhaite modifier ma commande.",
  "labels": {
    "intent": "ORDER_CHANGE",
    "sentiment": "NEUTRAL"
  },
  "review_status": "validated"
}
Multilingual Annotation Across 100+ Languages
Stepes supports multilingual text annotation across major global languages and regional variants where vocabulary, terminology, tone, usage, or cultural context can affect annotation decisions.
For large programs, centralized governance combines with distributed native-language execution so teams can scale multiple markets while maintaining common annotation standards.
Annotation Expertise for Specialized Content
Enterprise AI increasingly operates in domains where terminology and subject-matter context directly affect the meaning of the data. Stepes supports both general-purpose and specialized multilingual datasets.
Life Sciences & Healthcare
Medical entities, terminology, symptoms, procedures, clinical concepts, patient content, and other healthcare-related information.
Technology & Software
AI platforms, technical support content, product data, software terminology, developer workflows, and user-generated content.
Financial Services
Financial documents, customer communications, products, transactions, risk categories, and industry-specific terminology.
Legal
Entity annotation, concept tagging, document classification, and legal-language applications where precise terminology and context matter.
eCommerce & Retail
Product taxonomy, search relevance, query intent, customer-review sentiment, product categorization, and marketplace content labeling.
Industrial & Manufacturing
Technical terminology, components, maintenance content, products, equipment, and support cases for specialized industrial systems.
Why Global AI Teams Choose Stepes
Multilingual AI data requires more than scaling an English annotation process into additional languages. Stepes combines language expertise, structured AI-data workflows, and global execution to help organizations build datasets that remain useful and consistent across markets.
Built for Multilingual AI
Language, terminology, cultural context, regional variation, and real-world usage are treated as part of dataset design rather than an afterthought.
Task-Matched Human Expertise
Native-language annotators, professional linguists, and domain specialists are matched to the actual complexity and risk of each project.
Consistent Global Annotation
Shared schemas, centralized guidelines, calibration, reviewer alignment, and documented decisions help maintain comparable labels across markets.
Structured Quality Controls
Programs can incorporate calibration, overlap, gold-standard checks, validation, secondary review, agreement analysis, and adjudication according to project requirements.
Flexible Schemas & Workflows
Stepes supports customer-defined taxonomies, labels, decision rules, data structures, delivery formats, and project-specific workflows.
Connected Multilingual AI Data Services
Extend the same multilingual operating model across data creation, conversational AI, voice data, LLM evaluation, output review, and ongoing model improvement.
Multilingual Text Annotation FAQs
Common questions about annotation scope, multilingual quality, custom schemas, delivery formats, and how annotation differs from LLM evaluation and AI output review.
Text annotation adds structured labels or metadata to unstructured text so artificial intelligence and machine-learning systems can learn from, classify, retrieve, or analyze the information. Common tasks include named entity recognition, span annotation, sentiment analysis, intent classification, text categorization, semantic relationships, content safety labeling, and search relevance annotation.
Multilingual text annotation applies structured labels across text in multiple languages and locales. Unlike simply translating an English dataset, multilingual annotation must account for differences in grammar, terminology, entities, idioms, intent expression, cultural context, and regional language use.
Translation converts content from one language into another while preserving meaning. Annotation keeps the underlying text and adds structured labels, spans, categories, attributes, or relationships that AI systems can use. Translation and annotation can also be combined within the same multilingual AI-data program when needed.
Stepes supports named entity recognition, span annotation, intent classification, sentiment and emotion labeling, text classification, multi-label categorization, taxonomy tagging, semantic relationships, search relevance, content safety and moderation, preference and response labeling, and domain-specific annotation. Custom schemas can also be supported.
Languages differ in grammar, morphology, word boundaries, terminology, entity conventions, cultural references, sentiment expression, and patterns of user intent. Annotation rules designed for English may therefore require adapted examples, native-language calibration, and additional edge-case guidance in other markets.
Stepes uses structured workflows that can include shared guidelines, calibration, native-language reviewer alignment, secondary review, automated validation, inter-annotator agreement analysis, and adjudication. Legitimate language-specific differences can be documented while preserving common global definitions wherever possible.
Yes. Stepes can work with existing schemas, labels, taxonomies, examples, and decision rules, or support customer-defined entity types, intent hierarchies, classification systems, moderation policies, relevance scales, relationship structures, and metadata fields. We can also review existing guidance from a multilingual perspective before production begins.
Yes. Depending on project requirements, teams can include professional linguists and domain specialists with experience in life sciences, healthcare, legal, finance, technology, manufacturing, and other technical fields.
Stepes can support common structured formats such as JSON, JSONL, CSV, TSV, XML, spreadsheets, annotation-platform exports, and customer-defined schemas. Specific fields, identifiers, span structures, relationships, metadata, and validation requirements are defined during project setup.
Text annotation creates structured labeled data for training, fine-tuning, classification, retrieval, and related AI workflows. LLM evaluation measures model performance against defined criteria such as factuality, relevance, instruction adherence, safety, and fluency. AI output review focuses on reviewing, correcting, refining, or approving generated content for real-world use.
Turn Global-Language Content Into Model-Ready AI Data
Whether you need a pilot dataset in a few languages or an ongoing annotation program across global markets, Stepes can help define the workflow, calibrate contributors, scale production, validate quality, and deliver structured data aligned with your AI pipeline.