
Multilingual LLM Evaluation Services
Benchmark and improve large language model performance across languages, markets, domains, and real-world use cases with qualified native-language evaluators, structured scoring frameworks, and scalable quality controls.
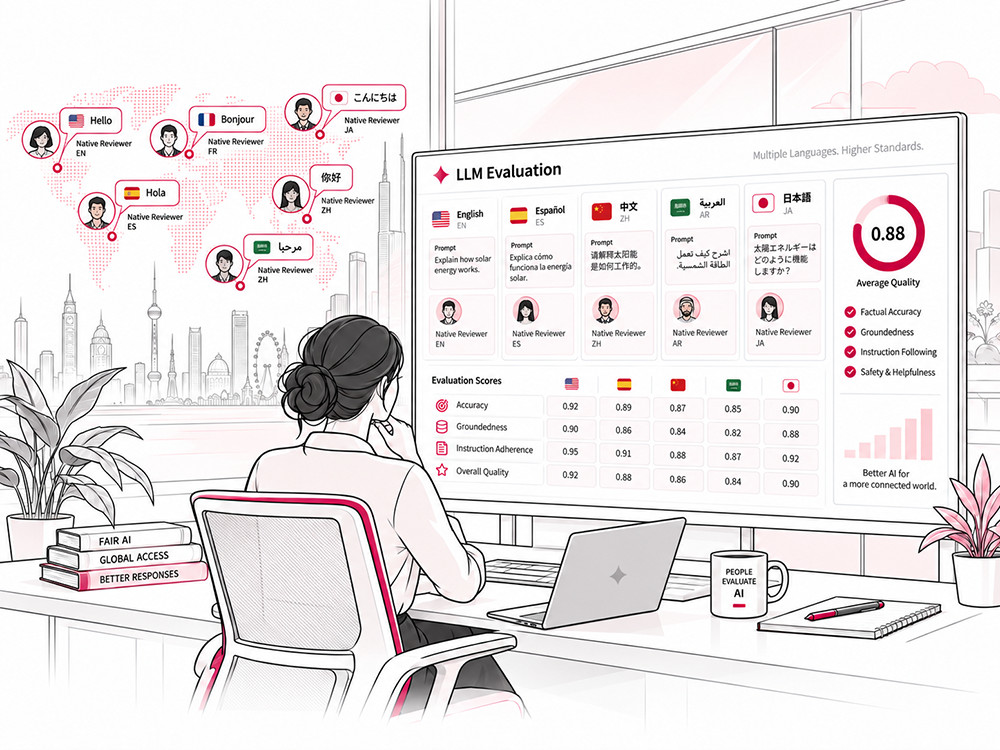
Evaluate AI Where Your Users Actually Use It
Large language models can perform differently across languages, locales, tasks, and domains. Strong English results do not automatically translate into equivalent factual accuracy, instruction following, cultural appropriateness, or user experience in every market.
Stepes combines native-language human judgment with structured evaluation methodologies to make these differences measurable. Human evaluation is especially valuable where quality depends on linguistic nuance, cultural interpretation, domain knowledge, subjective preference, or complex context.
Automated metrics and model-based judges can add speed and coverage. Calibrated human evaluation adds trusted reference judgments that help validate, investigate, and improve multilingual performance.
Multilingual Evaluation Across LLM Tasks and Applications
Stepes evaluates individual model responses, end-to-end AI systems, model releases, benchmark datasets, and multilingual production workflows across a wide range of generative AI tasks.
Prompt and Response Evaluation
Measure whether model responses are accurate, relevant, complete, clear, useful, and aligned with the requested task across languages.
Pairwise Preference Evaluation
Compare two or more responses against the same prompt to determine which better satisfies defined evaluation criteria.
Multi-Turn Conversation Evaluation
Assess context retention, coherence, naturalness, consistency, user-intent alignment, and conversational behavior across multiple exchanges.
RAG and Grounded Response Evaluation
Evaluate whether generated answers accurately reflect supplied or retrieved information and identify unsupported, omitted, or distorted claims.
Summarization and Rewriting Evaluation
Assess factual accuracy, completeness, meaning preservation, conciseness, readability, and compliance with requested formats or instructions.
Multilingual Translation and Localization Evaluation
Measure semantic accuracy, fluency, terminology, locale appropriateness, cultural relevance, and instruction adherence in AI-generated multilingual content.
Domain-Specific AI Evaluation
Evaluate specialized outputs where terminology, professional conventions, source knowledge, or regulated subject matter materially affect quality.
Model and Version Comparison
Benchmark models, prompts, fine-tuned versions, or successive releases against consistent multilingual test sets and scoring criteria.
Measure the Dimensions That Define Model Quality
There is no single score that captures every aspect of LLM performance. Evaluation criteria can be configured around your application, users, domain, and risk profile.
Is the information correct and contextually appropriate?
Are claims supported by the prompt, source material, or retrieved content?
Does the response directly address the user’s request?
Does it include the information needed to answer the task adequately?
Does the model follow constraints, format, tone, terminology, and task instructions?
Is the response fluent, grammatical, natural, readable, and idiomatic?
Does the output reflect appropriate regional usage, conventions, and context?
Does the model use technical, approved, branded, or industry-specific terms correctly?
Does the output meet defined safety, policy, and application-specific criteria?
Does the model behave comparably across equivalent languages, prompts, and tasks?
Native-Language Human Evaluation, Calibrated for Consistency
Effective multilingual evaluation matches evaluator qualifications to the judgment being made, then supports those decisions with clear rubrics, calibration, review, and adjudication.
Match Evaluators to the Task
Depending on the program, evaluation teams can include qualified native speakers, professional linguists, bilingual reviewers, specialized AI evaluators, and subject-matter experts.
- Language and locale qualification
- Task-specific screening
- Subject-matter qualification
- Project guidelines and training
- Representative qualification samples
- Ongoing quality monitoring
Make Human Judgment More Consistent
Structured rubrics and calibration help reduce unnecessary reviewer variation while preserving the human judgment required for nuanced multilingual evaluation.
- Custom scoring rubrics
- Evaluator guidelines and examples
- Calibration sets
- Gold or reference examples where appropriate
- Evaluator agreement checks where appropriate
- Senior review and adjudication
One Evaluation Framework Across Languages and Markets
Stepes combines centralized evaluation standards with language-specific guidance so results remain comparable without ignoring genuine linguistic, cultural, and locale differences.
Build Multilingual Evaluation Into the AI Lifecycle
Move beyond one-time testing with a repeatable framework for benchmarking models, validating releases, identifying regressions, and tracking multilingual performance over time.
Design the Evaluation
Define target tasks, languages, benchmark data, scoring methodology, evaluator requirements, and reporting needs.
Pilot and Calibrate
Test the rubric on representative examples, align evaluators, refine ambiguous criteria, and establish a baseline.
Benchmark Models
Evaluate one or more models using consistent multilingual test sets and comparable scoring criteria.
Analyze Errors
Classify failures by language, task, error type, severity, and model version to reveal recurring patterns.
Validate New Releases
Re-run representative benchmarks after model, prompt, fine-tuning, retrieval, or application changes.
Monitor Performance
Support recurring multilingual evaluation as your models and production systems continue to evolve.
Combine Human Judgment With Automated Evaluation
Modern AI teams increasingly use automated metrics, deterministic tests, model-based judges, and human evaluation together. The strongest programs assign each method to the work it does best.
Automated Evaluation
Useful for high-volume, repeatable, or deterministic checks where scoring criteria can be applied consistently at scale.
- Automated metrics and test suites
- Rule-based and deterministic checks
- LLM-as-a-judge workflows
- Rapid coverage across large datasets
Human Evaluation
Especially valuable when quality depends on language nuance, cultural interpretation, domain expertise, factual judgment, or subjective preference.
- Human reference benchmarks
- Cultural and linguistic quality
- Complex and ambiguous edge cases
- High-risk or domain-specific review
Use multilingual human judgments to validate scoring approaches, investigate disagreements, calibrate model-based evaluators, and audit automated evaluation results.
From Reliable Multilingual Benchmarks to Actionable Evaluation Data
Evaluation quality depends on both what you test and how you structure the resulting judgments. Stepes helps create multilingual test content that reflects real target-language usage and turn human evaluation into data your AI teams can analyze.
Build Reliable Multilingual Benchmarks
Multilingual test sets should preserve the intended task while sounding natural in each target language. Stepes can create, localize, and validate benchmark content so language artifacts do not obscure the model behavior you are trying to measure.
Turn Human Evaluation Into Actionable Model Data
Evaluation results are most useful when they can be analyzed systematically. Stepes structures reviewer judgments so AI teams can compare models, investigate failures, and prioritize improvements.
Depending on your evaluation design, deliverables can include response-level scores, preference decisions, multidimensional scorecards, issue classifications, severity levels, evaluator comments, adjudicated decisions, language comparisons, benchmark summaries, and structured evaluation datasets.
See How Multilingual Model Performance Becomes Measurable
Structured evaluation records turn subjective impressions into comparable data that can be analyzed by model, version, language, task, issue type, and quality dimension.
Identify Where and Why Models Fail
A model score can show that performance changed. A structured error taxonomy helps explain why and reveals recurring weaknesses across languages and releases.
Evaluate Specialized AI With Specialized Expertise
General fluency does not guarantee accuracy in technical or regulated domains. Evaluator qualifications can be aligned with the risk, complexity, terminology, and subject matter of each program.
Life Sciences & Healthcare
Clinical, medical, scientific, regulatory, patient-facing, and healthcare AI outputs requiring accurate terminology and contextual judgment.
Explore Life Sciences & HealthcareMedical Devices
Device terminology, IFUs, labeling, software interfaces, technical documentation, training, and specialized product content.
Explore Medical DevicesLegal
Legal and compliance-related outputs where meaning, terminology, completeness, source alignment, and document context matter.
Explore LegalFinancial Services
Financial terminology, customer communications, reports, disclosures, support content, and other knowledge-intensive use cases.
Explore Financial ServicesTechnology & Software
Product support, technical documentation, conversational systems, interfaces, developer content, and enterprise AI applications.
Explore Technology & SoftwareManufacturing & Engineering
Technical terminology, product documentation, troubleshooting, service content, and industrial AI use cases requiring domain expertise.
Explore Manufacturing & EngineeringBuilt for Repeatable, Governed AI Programs
Large multilingual evaluation programs need more than individual reviewer judgments. They require structured workflows, secure handling of proprietary data, consistent standards, scalable evaluator management, and actionable reporting.
Build multilingual teams across languages, locales, domains, and task types under centralized program management.
Support proprietary prompts, outputs, reference materials, and benchmark data through controlled enterprise workflows.
Maintain shared criteria, evaluator qualifications, guidelines, calibration, escalation, and reporting across languages.
Create structured scoring and review records that support analysis, governance, and repeatable model-quality decisions.
Reusable multilingual benchmarks can help compare model releases, prompt changes, RAG updates, fine-tuning, guardrails, and application changes so teams can identify language-specific improvements and regressions over time.
Why Stepes for Multilingual LLM Evaluation
Stepes combines global language expertise with structured AI data workflows to help organizations evaluate model performance beyond English.
Multilingual Depth
Native-language resources across 100+ languages, including regional variants and emerging-market requirements.
Qualified Human Evaluation
Match evaluator skills to each task, from native-language preference judgments to specialized domain review.
Domain Expertise
Support complex AI applications with resources who understand specialized terminology and subject matter.
Controlled Evaluation
Apply rubrics, guidelines, calibration, adjudication, and quality controls to make judgments more actionable.
Global Scale
Coordinate multilingual evaluation programs centrally while preserving language-specific requirements.
Structured Evaluation Data
Convert reviewer judgments into scores, classifications, findings, and benchmark data for model improvement.
Multilingual LLM Evaluation FAQs
Answers to common questions about human evaluation, multilingual benchmarking, model comparison, scoring frameworks, and continuous evaluation.
Multilingual LLM evaluation is the structured process of measuring how large language models perform across different languages, locales, tasks, and use cases. Evaluation can include accuracy, factuality, groundedness, relevance, instruction adherence, linguistic quality, cultural appropriateness, terminology, safety, and other quality dimensions.
Model performance can vary by language because of differences in training data, linguistic structure, cultural context, terminology, scripts, prompts, and domain coverage. Evaluating only in English may not reveal issues that appear when the same AI system is used by people in other languages and markets.
Rubrics can include accuracy, factuality, groundedness, relevance, completeness, instruction adherence, fluency, linguistic quality, terminology, cultural appropriateness, consistency, safety, and other application-specific criteria. Scoring frameworks can be customized to your model and use case.
Yes. Common evaluation datasets and scoring criteria can be used to compare different models, configurations, prompts, or releases across languages, helping identify performance differences and language-specific strengths or weaknesses.
Evaluation programs can use defined scoring rubrics, reviewer guidelines, qualification tasks, calibration examples, quality monitoring, senior review, and adjudication. For appropriate tasks, evaluator agreement can also be monitored to identify unclear criteria or areas requiring additional calibration.
Pairwise preference evaluation presents evaluators with two model outputs for the same prompt and asks them to determine which response better satisfies defined criteria. The resulting preference data can support model comparison, ranking, fine-tuning, alignment, and other AI development workflows.
LLM evaluation measures how well a model or AI system performs across representative tasks, datasets, languages, and quality criteria. AI output review focuses on individual AI-generated content and determines whether that content is accurate, clear, appropriate, and ready for real-world use. The two services are complementary but address different business needs.
Yes. Human evaluation can complement automated methods by providing reference judgments, validating scoring approaches, investigating disagreements, evaluating nuanced linguistic and cultural criteria, and reviewing complex or high-risk cases.
Yes. A reusable multilingual benchmark can be applied to new model releases, prompt changes, fine-tuning updates, RAG changes, and other system modifications. Comparing results over time can help identify improvements and regressions by language, task, and quality dimension.
Yes. Depending on project requirements, Stepes can support multilingual prompt creation, benchmark translation and localization, linguistic QA, reference-answer review, terminology validation, cultural adaptation, and native-language evaluation content development.
Build a Multilingual Evaluation Program That Scales
Compare models, validate releases, evaluate RAG performance, build preference data, and measure quality across languages with qualified human evaluators and structured evaluation frameworks.